Adaptive inference.
For Apple Silicon.
A local inference framework with MLX at its core. Run through CLI, Python or streamed chat API. Explore DeepInfer-inspired scheduling with a clear view of every execution cycle.
Local workflows.
Inspectable execution.
Models are execution objects, not the framework definition. Start with the verified 9B demonstration, reuse context and explore an adaptive cycle that accounts for drafting, verification and recovery.
Make the budget a decision.
A DeepInfer MTPVarlen-derived scheduler uses observed acceptance and complete-cycle cost to choose the next draft budget. Decisions can be replayed against the original C++ reference.
Preserve the exact state.
Hybrid attention and recurrent state travel together. Checkpoint, restore and replay the consumed prefix when a draft is rejected, keeping mutable branches isolated.
Carry context forward.
Native MLX-LM LRU reuse and exact hybrid snapshots share a bounded cache interface. Verified message boundaries create reusable checkpoints for repeated and changed-tail requests.
From design to running code.
Real Qwen3.5-9B-8bit execution on an M4 Pro. These milestones validate scheduler correspondence, token preservation and a practical local context workload.
Native batching. A complete local workflow.
The local 0.1.0a3 candidate uses MLX-LM native batching by default, with bounded admission, serial capability fallback, streamed responses and cancellation recovery.
46/46 actual-model service checks passed. Recorded three-process native paired-task median: 124.09 ms, on the audited SmolLM2 pair workload. Scope and complete comparisons are available in the reports.
Many requests.
One accountable lifecycle.
Bounded admission, per-request state and cancellation recovery now connect to real joint target verification. The joint service passed 35/35 functional checks with distinct SmolLM2 360M target and 135M draft models, including concurrent requests, actual token SSE and recovery after cancellation.
330 portable tests + 48 real Metal tests passed at this checkpoint. The small models are engineering controls; Qwen3.5-9B remains the primary demonstration. Default service uses baseline; joint execution is explicit opt-in.
More control.
At every execution step.
Model and cache capabilities feed bounded request ticks. Joint budgets turn observed acceptance and measured cost into actual variable-length verification buckets. Separate optional Python paths batch draft calls and trim audited dense KV state, with explicit recovery boundaries.
338 portable tests + 76 real Metal tests passed at the dense execution checkpoint. Dense fast paths are explicit Python options; the default API retains its verified baseline and separate joint-service entry.
Your next inference runs here.
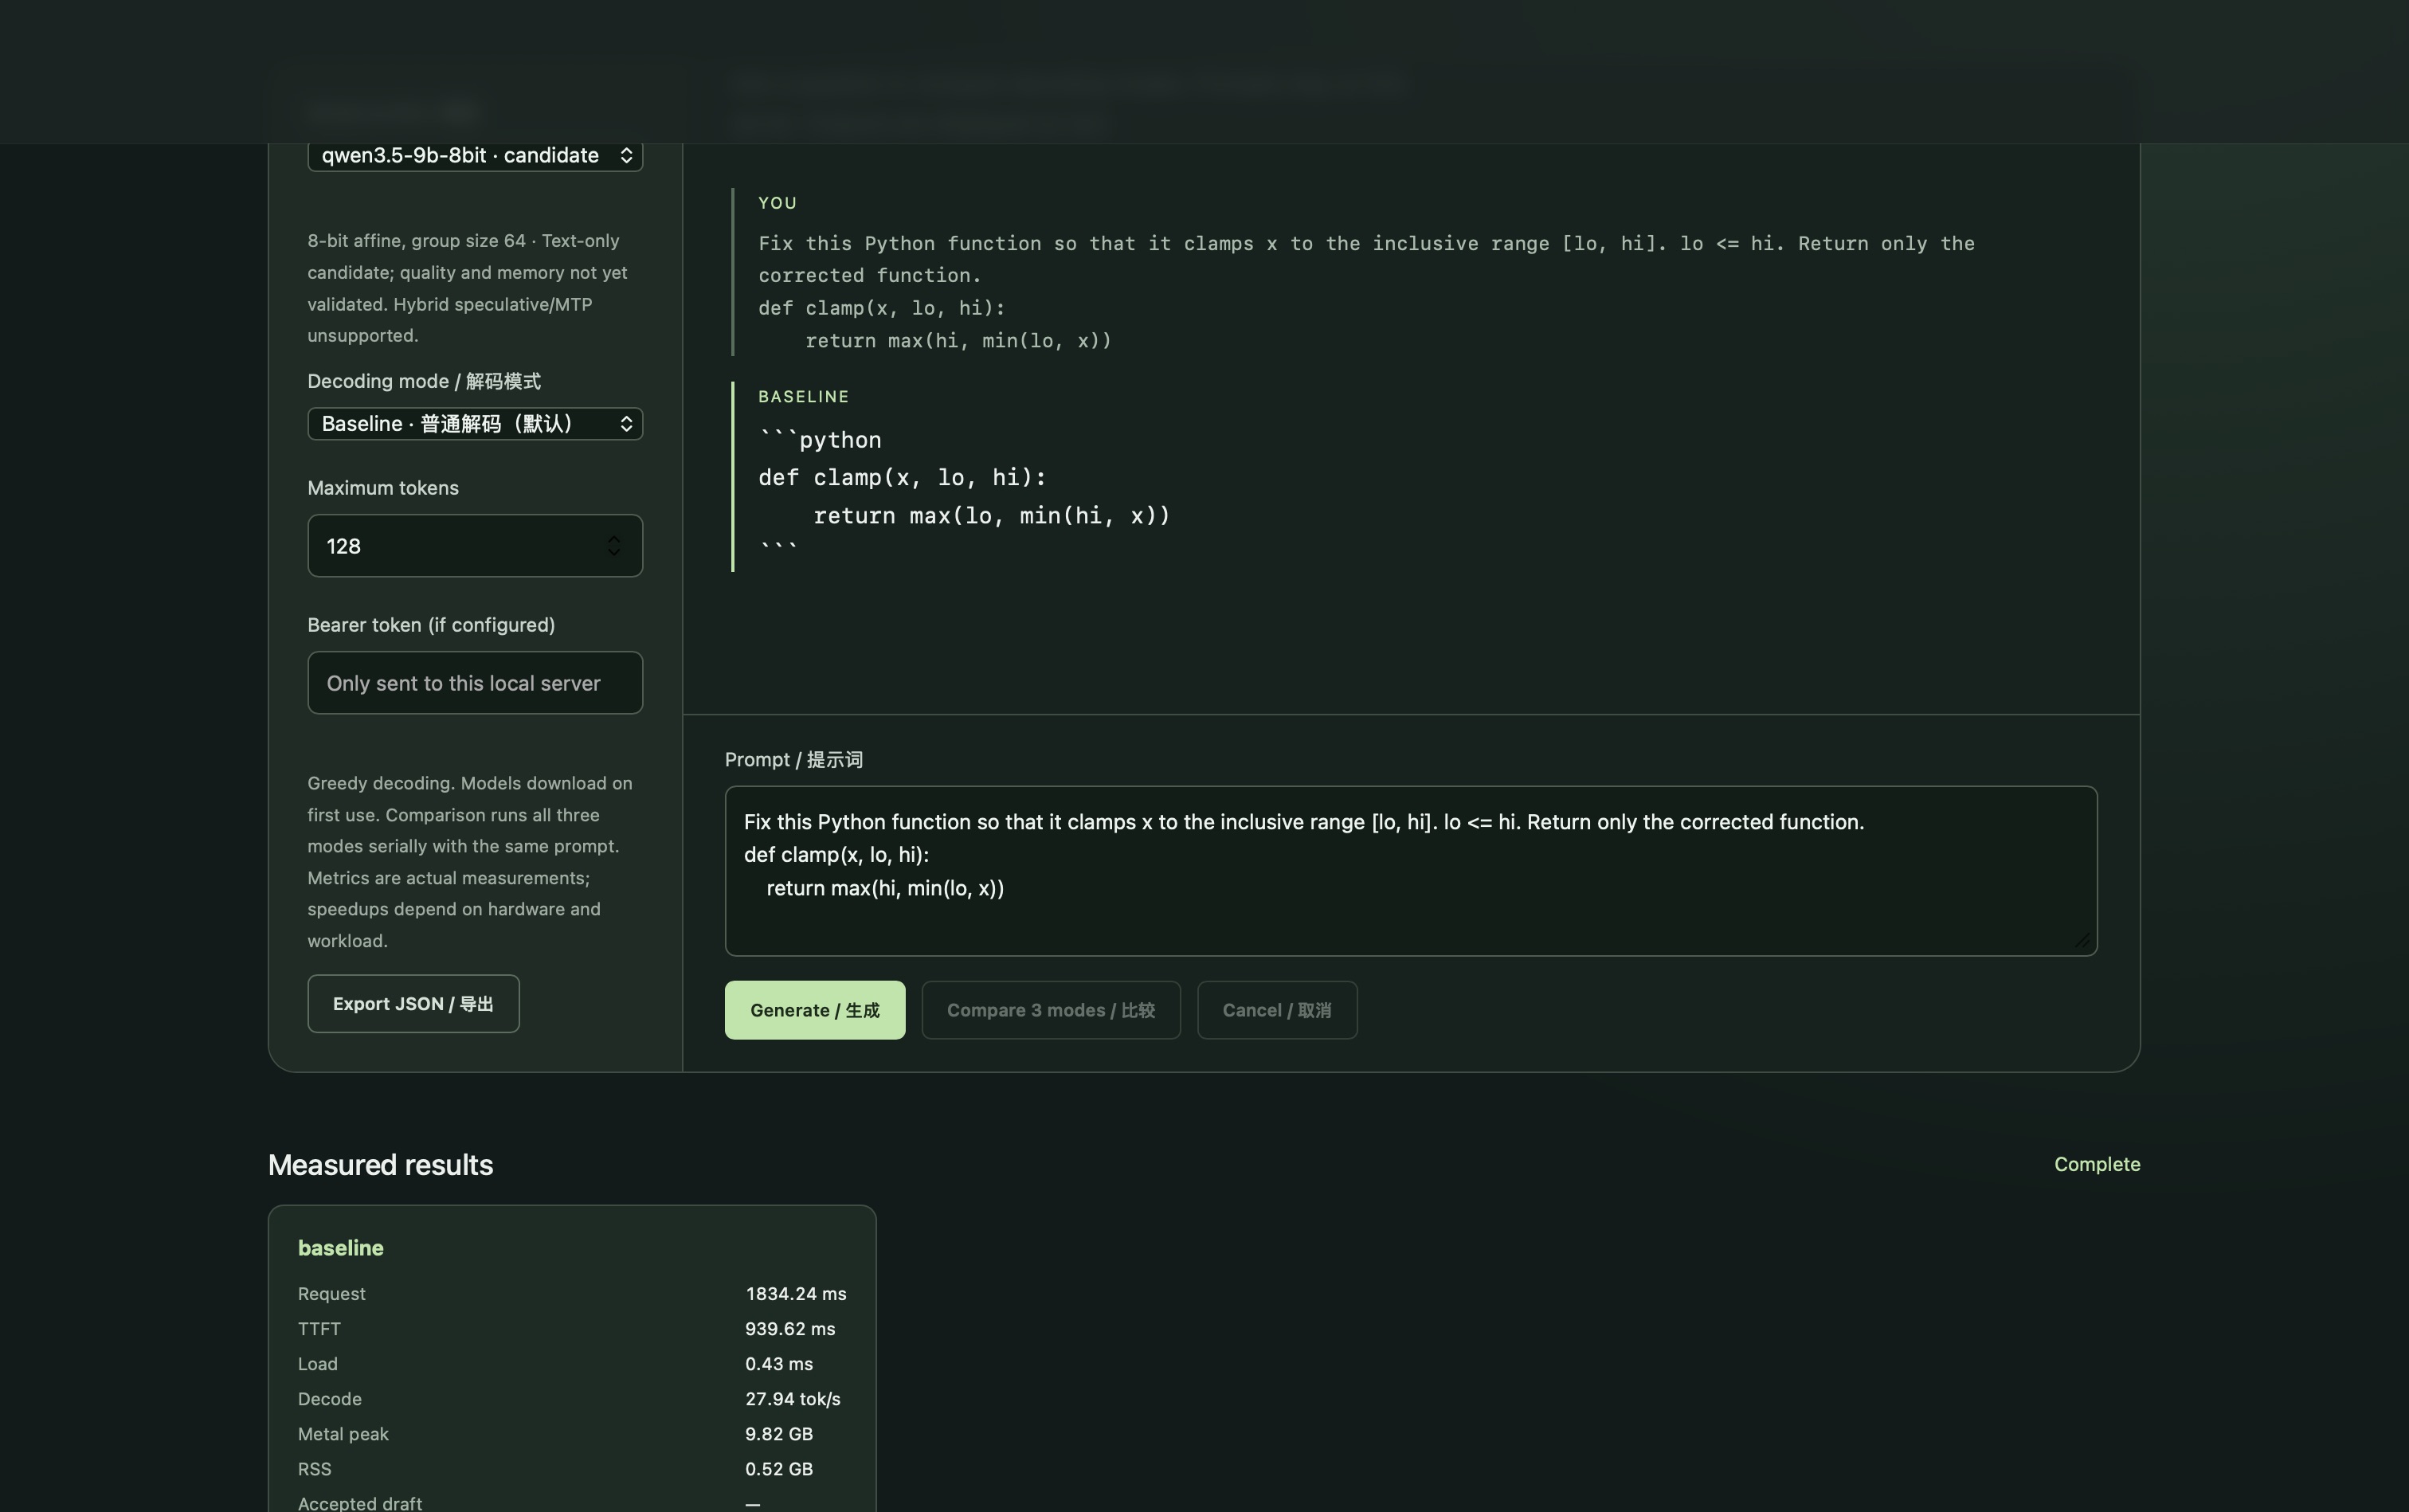
Apple Silicon · Python 3.12 / 3.13 · uv. Start the bundled local UI and API with the locked 9B model.
git clone --branch main --single-branch https://github.com/ZEVIN17/deepinfer-mac.git
cd deepinfer-mac
uv sync --frozen --extra mlx
uv run deepinfer-mac doctor
uv run deepinfer-mac models --download qwen3.5-9b-8bit --target-only
uv run deepinfer-mac serveDoctor reports Metal, Python, available memory and disk.
Visit http://127.0.0.1:8765 and select qwen3.5-9b-8bit. The default path is baseline generation.
Use CLI, streamed API or the bundled browser UI. Explore the explicit adaptive entry in the architecture guide.
A new model family.
The same working interface.
SmolLM2-135M-Instruct-8bit has completed real baseline/native token matching for English and Chinese inputs, dense cache branch reuse, CLI generation, API and SSE checks. Registration, explicit fallback, cancellation and recovery were exercised with the actual model.
Scope: baseline integration of this 135M dense model. Qwen3.5-9B-8bit remains the primary demonstration. These checks establish integration correctness.
One framework.
Explicit capabilities.
The 9B model is our primary demonstration. Baseline compatibility and optimized execution are validated separately, across dense and hybrid state structures.
| Model / path | Status | Scope |
|---|---|---|
| Qwen3.5-9B-8bit | Verified CLI / API / UI | Hybrid · explicit adaptive |
| Qwen3.5-9B-4bit | Verified baseline / native controls | Hybrid · quality / memory control |
| Qwen3-14B-4bit | Verified baseline / native controls | Dense · engineering control |
| Qwen3-4B | Verified regression path | Dense · fixed / adaptive |
| SmolLM2-135M-Instruct-8bit | Verified baseline / cache / CLI / API / SSE | Dense · configurable model adapter |
| Other custom models | Per-model acceptance required | Capability-gated model path / repo integration |
| Joint verification service | 35/35 real-model service checks | 360M target + 135M draft · dense research pair |
Verified describes the listed path. Public 9B UI/API use baseline; hybrid adaptive decoding is explicit opt-in. Bounded multi-request execution and joint verification have separate explicit opt-in entries. The small-model joint path validates service behavior.
Compatibility and execution modes ↗A small engine.
A clear line of sight.
Trace the method to its source, inspect the implementation and make the next contribution.